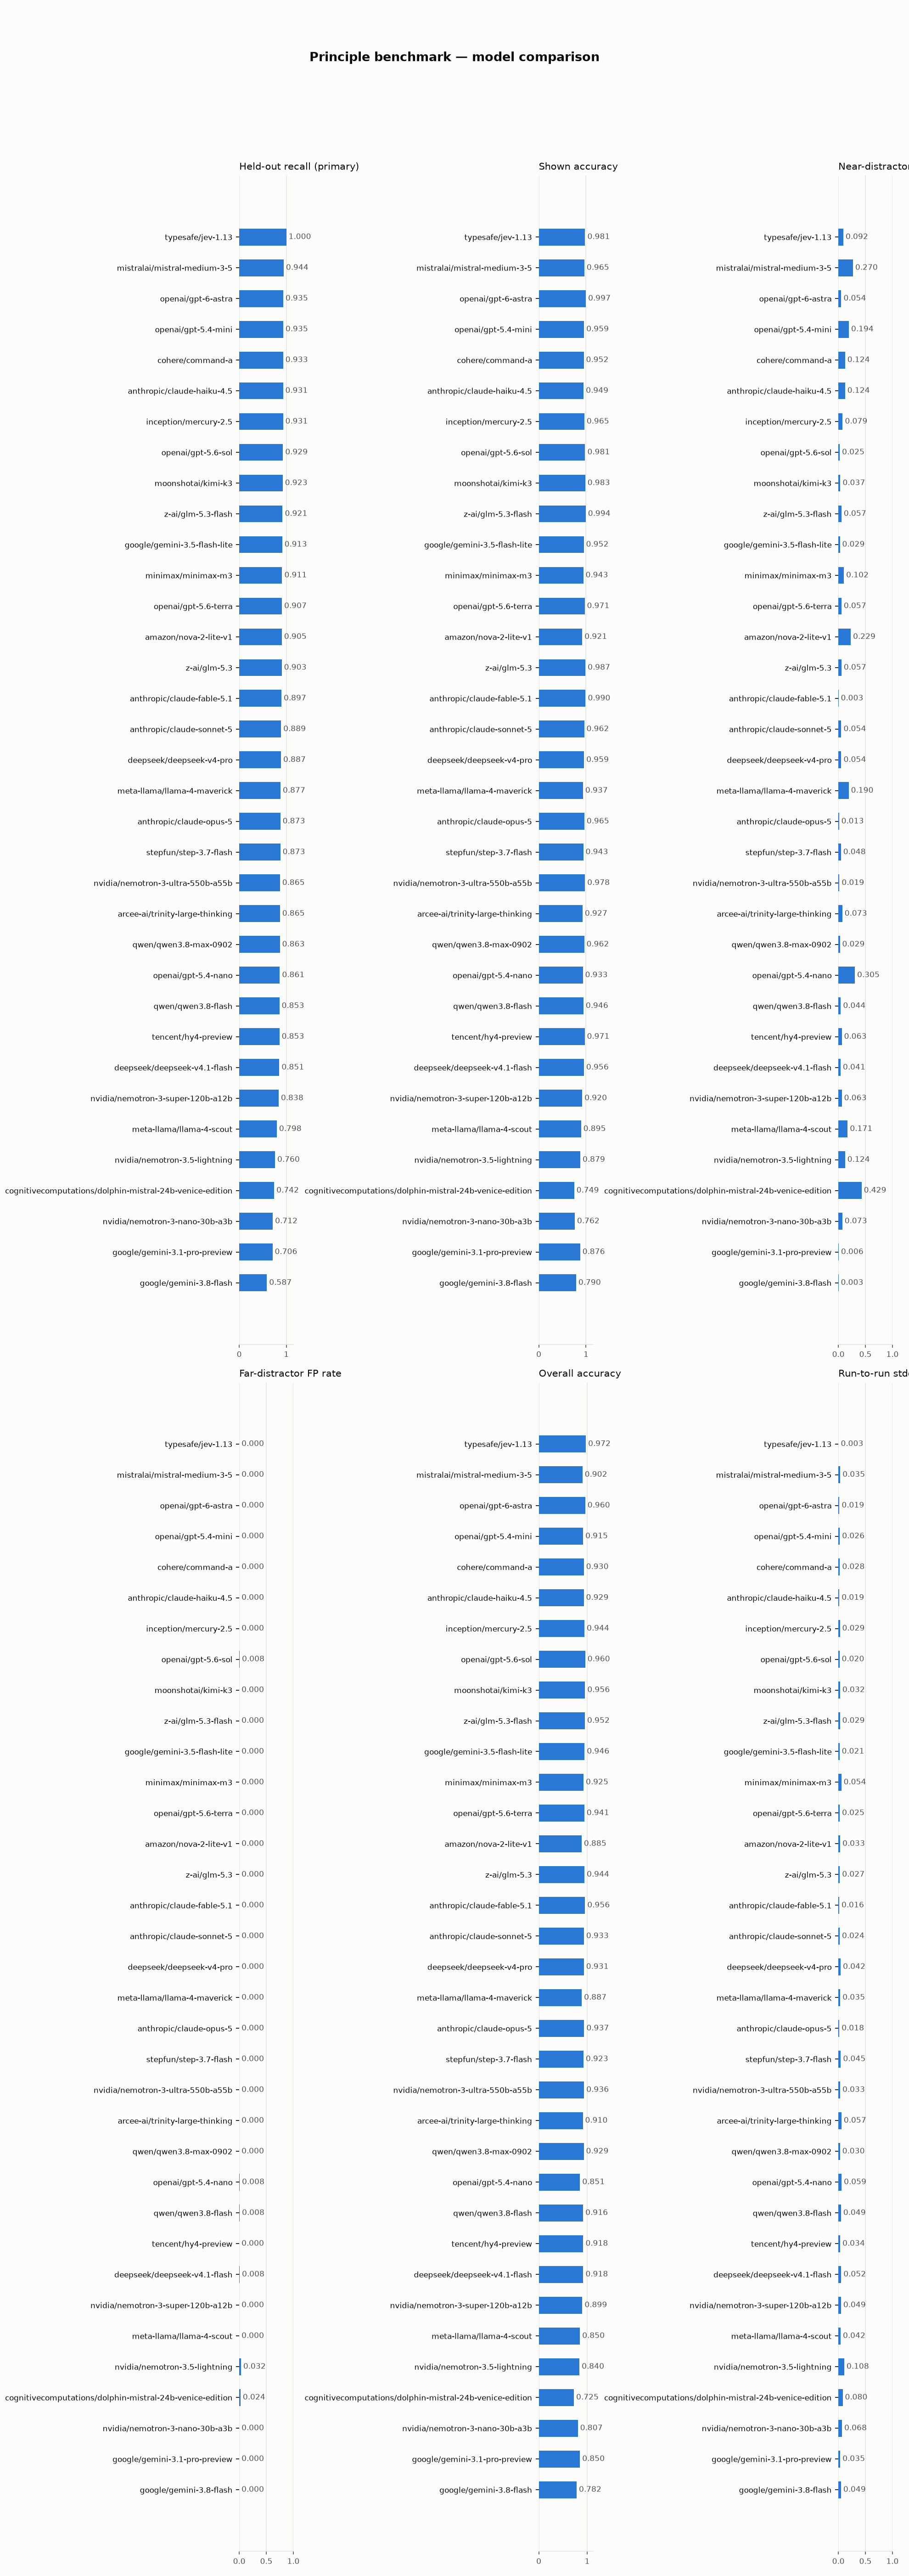
Models ranked by held-out recall — how well the stated principle
recovers matching statements the model never saw. False-positive rates keep that
number honest: a vague accept-everything principle scores high recall and high FP
together.
| Model | Suites | Held-out recall | Shown acc | FP (near) | FP (far) | Overall | Run stdev | Malformed | Over limit |
|---|
| typesafe/jev-1.13 | 21 | 1.000 | 0.981 | 0.092 | 0.000 | 0.972 | 0.003 | 0 | 0 |
| mistralai/mistral-medium-3-5 | 21 | 0.944 | 0.965 | 0.270 | 0.000 | 0.902 | 0.035 | 0 | 0 |
| openai/gpt-6-astra | 21 | 0.935 | 0.997 | 0.054 | 0.000 | 0.960 | 0.019 | 0 | 0 |
| openai/gpt-5.4-mini | 21 | 0.935 | 0.959 | 0.194 | 0.000 | 0.915 | 0.026 | 0 | 0 |
| cohere/command-a | 21 | 0.933 | 0.952 | 0.124 | 0.000 | 0.930 | 0.028 | 0 | 0 |
| anthropic/claude-haiku-4.5 | 21 | 0.931 | 0.949 | 0.124 | 0.000 | 0.929 | 0.019 | 0 | 0 |
| inception/mercury-2.5 | 21 | 0.931 | 0.965 | 0.079 | 0.000 | 0.944 | 0.029 | 0 | 1 |
| openai/gpt-5.6-sol | 21 | 0.929 | 0.981 | 0.025 | 0.008 | 0.960 | 0.020 | 0 | 0 |
| moonshotai/kimi-k3 | 20 | 0.923 | 0.983 | 0.037 | 0.000 | 0.956 | 0.032 | 0 | 0 |
| z-ai/glm-5.3-flash | 21 | 0.921 | 0.994 | 0.057 | 0.000 | 0.952 | 0.029 | 0 | 0 |
| google/gemini-3.5-flash-lite | 21 | 0.913 | 0.952 | 0.029 | 0.000 | 0.946 | 0.021 | 0 | 0 |
| minimax/minimax-m3 | 21 | 0.911 | 0.943 | 0.102 | 0.000 | 0.925 | 0.054 | 0 | 0 |
| openai/gpt-5.6-terra | 21 | 0.907 | 0.971 | 0.057 | 0.000 | 0.941 | 0.025 | 0 | 0 |
| amazon/nova-2-lite-v1 | 21 | 0.905 | 0.921 | 0.229 | 0.000 | 0.885 | 0.033 | 0 | 0 |
| z-ai/glm-5.3 | 21 | 0.903 | 0.987 | 0.057 | 0.000 | 0.944 | 0.027 | 0 | 0 |
| anthropic/claude-fable-5.1 | 21 | 0.897 | 0.990 | 0.003 | 0.000 | 0.956 | 0.016 | 0 | 0 |
| anthropic/claude-sonnet-5 | 21 | 0.889 | 0.962 | 0.054 | 0.000 | 0.933 | 0.024 | 0 | 4 |
| deepseek/deepseek-v4-pro | 21 | 0.887 | 0.959 | 0.054 | 0.000 | 0.931 | 0.042 | 0 | 0 |
| meta-llama/llama-4-maverick | 21 | 0.877 | 0.937 | 0.190 | 0.000 | 0.887 | 0.035 | 0 | 0 |
| anthropic/claude-opus-5 | 21 | 0.873 | 0.965 | 0.013 | 0.000 | 0.937 | 0.018 | 0 | 1 |
| stepfun/step-3.7-flash | 21 | 0.873 | 0.943 | 0.048 | 0.000 | 0.923 | 0.045 | 0 | 0 |
| nvidia/nemotron-3-ultra-550b-a55b | 21 | 0.865 | 0.978 | 0.019 | 0.000 | 0.936 | 0.033 | 0 | 0 |
| arcee-ai/trinity-large-thinking | 21 | 0.865 | 0.927 | 0.073 | 0.000 | 0.910 | 0.057 | 0 | 0 |
| qwen/qwen3.8-max-0902 | 21 | 0.863 | 0.962 | 0.029 | 0.000 | 0.929 | 0.030 | 0 | 0 |
| openai/gpt-5.4-nano | 21 | 0.861 | 0.933 | 0.305 | 0.008 | 0.851 | 0.059 | 0 | 0 |
| qwen/qwen3.8-flash | 21 | 0.853 | 0.946 | 0.044 | 0.008 | 0.916 | 0.049 | 0 | 0 |
| tencent/hy4-preview | 21 | 0.853 | 0.971 | 0.063 | 0.000 | 0.918 | 0.034 | 0 | 0 |
| deepseek/deepseek-v4.1-flash | 21 | 0.851 | 0.956 | 0.041 | 0.008 | 0.918 | 0.052 | 0 | 0 |
| nvidia/nemotron-3-super-120b-a12b | 20 | 0.838 | 0.920 | 0.063 | 0.000 | 0.899 | 0.049 | 0 | 0 |
| meta-llama/llama-4-scout | 21 | 0.798 | 0.895 | 0.171 | 0.000 | 0.850 | 0.042 | 0 | 0 |
| nvidia/nemotron-3.5-lightning | 21 | 0.760 | 0.879 | 0.124 | 0.032 | 0.840 | 0.108 | 0 | 0 |
| cognitivecomputations/dolphin-mistral-24b-venice-edition | 21 | 0.742 | 0.749 | 0.429 | 0.024 | 0.725 | 0.080 | 0 | 0 |
| nvidia/nemotron-3-nano-30b-a3b | 21 | 0.712 | 0.762 | 0.073 | 0.000 | 0.807 | 0.068 | 0 | 0 |
| google/gemini-3.1-pro-preview | 21 | 0.706 | 0.876 | 0.006 | 0.000 | 0.850 | 0.035 | 0 | 0 |
| google/gemini-3.8-flash | 21 | 0.587 | 0.790 | 0.003 | 0.000 | 0.782 | 0.049 | 0 | 0 |
| Model | shown=5 |
|---|
| typesafe/jev-1.13 | 1.000 |
| mistralai/mistral-medium-3-5 | 0.944 |
| openai/gpt-6-astra | 0.935 |
| openai/gpt-5.4-mini | 0.935 |
| cohere/command-a | 0.933 |
| anthropic/claude-haiku-4.5 | 0.931 |
| inception/mercury-2.5 | 0.931 |
| openai/gpt-5.6-sol | 0.929 |
| moonshotai/kimi-k3 | 0.923 |
| z-ai/glm-5.3-flash | 0.921 |
| google/gemini-3.5-flash-lite | 0.913 |
| minimax/minimax-m3 | 0.911 |
| openai/gpt-5.6-terra | 0.907 |
| amazon/nova-2-lite-v1 | 0.905 |
| z-ai/glm-5.3 | 0.903 |
| anthropic/claude-fable-5.1 | 0.897 |
| anthropic/claude-sonnet-5 | 0.889 |
| deepseek/deepseek-v4-pro | 0.887 |
| meta-llama/llama-4-maverick | 0.877 |
| anthropic/claude-opus-5 | 0.873 |
| stepfun/step-3.7-flash | 0.873 |
| nvidia/nemotron-3-ultra-550b-a55b | 0.865 |
| arcee-ai/trinity-large-thinking | 0.865 |
| qwen/qwen3.8-max-0902 | 0.863 |
| openai/gpt-5.4-nano | 0.861 |
| qwen/qwen3.8-flash | 0.853 |
| tencent/hy4-preview | 0.853 |
| deepseek/deepseek-v4.1-flash | 0.851 |
| nvidia/nemotron-3-super-120b-a12b | 0.838 |
| meta-llama/llama-4-scout | 0.798 |
| nvidia/nemotron-3.5-lightning | 0.760 |
| cognitivecomputations/dolphin-mistral-24b-venice-edition | 0.742 |
| nvidia/nemotron-3-nano-30b-a3b | 0.712 |
| google/gemini-3.1-pro-preview | 0.706 |
| google/gemini-3.8-flash | 0.587 |